The one-second CEFR verdict
You paste a paragraph you wrote in French. Two seconds later, an AI tells you it's B1, lists five mistakes, and suggests a rewrite. The whole thing feels magical — and slightly suspicious. Can AI CEFR grading actually match what a trained examiner would say, or is it a language model pattern-matching its way to a confident-sounding letter?
The question matters because a lot of language apps — ours included — now hand out CEFR estimates on learner writing. It's worth understanding what those numbers mean, what they miss, and how to use them without over-trusting them.
What CEFR grading actually measures
The Common European Framework of Reference sorts language proficiency into six bands, A1 through C2. On paper it looks like a ruler. In practice, it's a rubric: examiners look at range of vocabulary, grammatical accuracy, coherence, task completion, and register, then triangulate a level.
The tricky part is that CEFR was designed for human raters working with meaningful samples. A single short paragraph doesn't give an examiner much to work with — they'd normally want a longer piece, ideally across genres, before committing to a level. When an AI grades five sentences and returns "B2," it's making a much larger leap than a human would.
That doesn't automatically make it wrong. But it's worth naming.
What the new research says
A peer-reviewed 2026 study, Harnessing AI for CEFR-Aligned Writing Assessment, looked at how well a customised GPT could grade learner writing against CEFR. The short version: reasonably well, with caveats.
The model's grades correlated meaningfully with human raters, especially in the middle of the scale (B1–B2). It was less reliable at the extremes — sometimes over-generous with beginner writing that landed a lucky idiomatic phrase, sometimes under-scoring advanced writing that took stylistic risks. It also tended to reward surface fluency (smooth phrasing) more than a trained examiner would, and under-weight deeper task-completion criteria.
That pattern — solid in the middle, wobbly at the edges — matches what learners report anecdotally. If you're a comfortable B1, AI feedback is probably close to accurate. If you're at either extreme, take the level with a grain of salt.
Where AI feedback beats a human tutor
Once you accept the caveats, AI writing feedback has real advantages a human tutor doesn't:
- Speed. You get a mistake list in seconds, not next week.
- Volume. You can submit ten short paragraphs a day. No teacher is going to mark that.
- Consistency of criteria. A human marker on a bad day marks harder. The model doesn't have moods.
- Low stakes. You'll try weirder sentences when the feedback is private and instant.
That last one matters more than it sounds. A lot of intermediate learners plateau because they stop taking risks in writing — they stick to the constructions they already know. Frictionless feedback lets them try the subjunctive, get corrected, and try it again the next day without paying social cost.
Where it still lags
The study's findings line up with the honest limits of any AI grader in 2026:
- Task fidelity. If the prompt was "write a formal complaint letter" and you wrote a beautiful but casual paragraph, the model may miss that you failed the task.
- Cultural register. Politeness levels, formality, idiomatic appropriateness — these are among the last things models handle reliably.
- Long-range coherence. Across a full essay, human readers still track argument structure better than models do.
- Diagnostic depth. "Your use of the perfect tense is inconsistent" is more useful than "grammar: 7/10." Good feedback names the specific pattern, not just a score.
None of these are dealbreakers. They're reasons to treat the CEFR letter as a signal, not a verdict.
What good AI feedback should look like
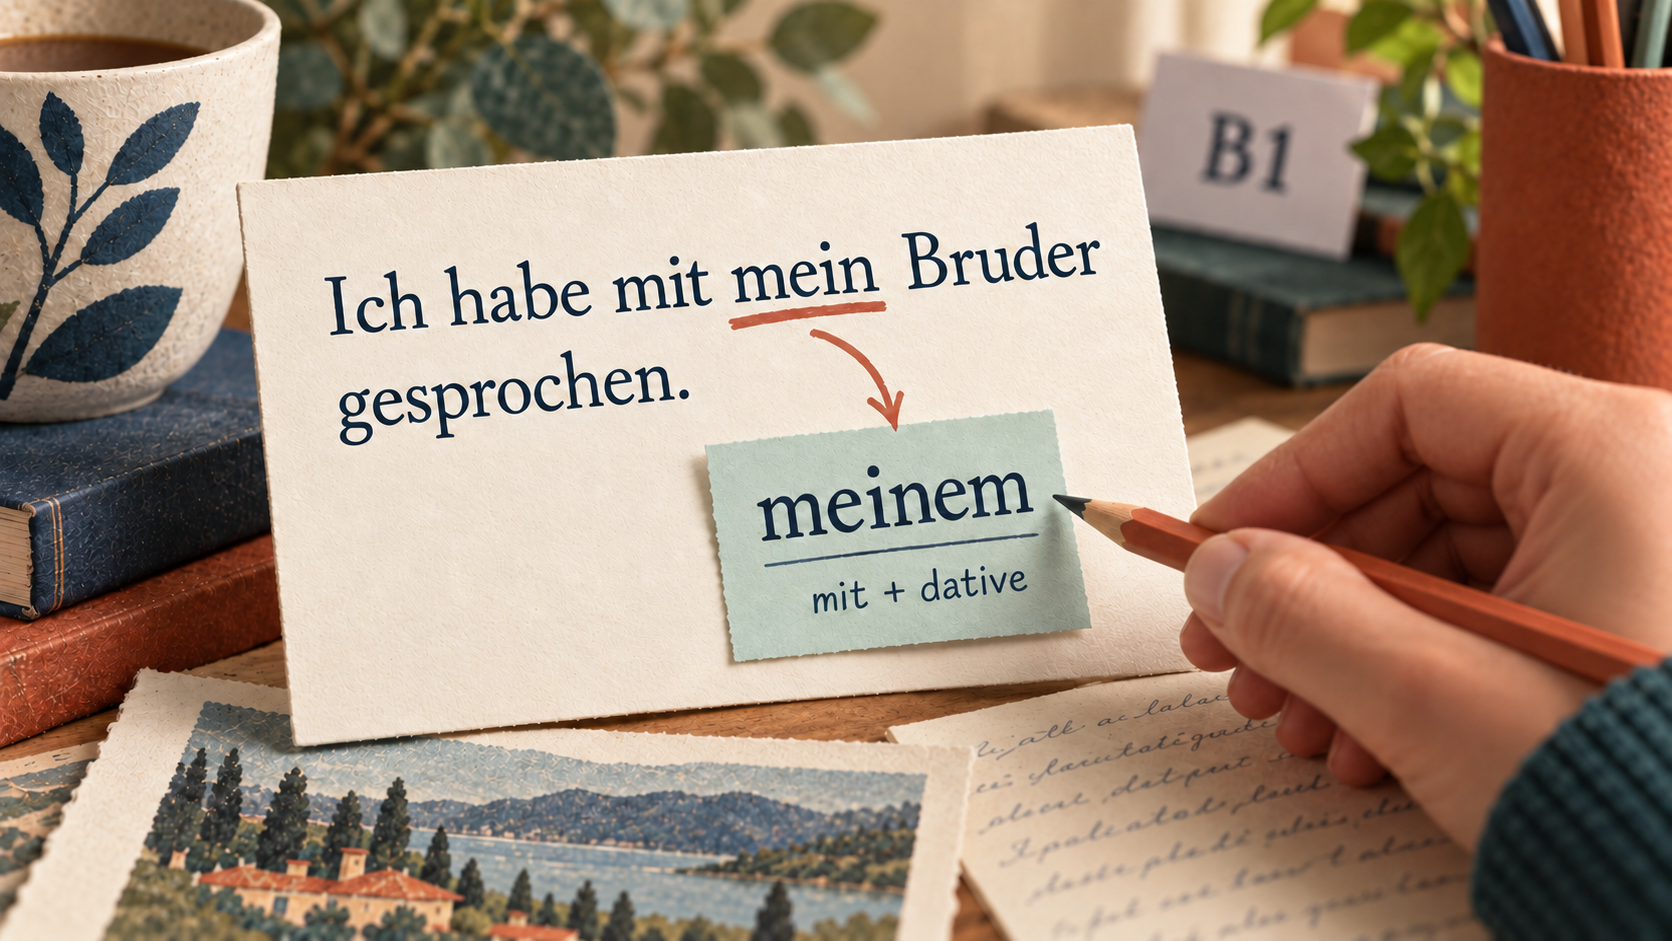
A CEFR estimate on its own is close to useless. What's actually helpful is the mistake list underneath it — the concrete, sentence-by-sentence notes you can act on tomorrow.
For example, feedback on a German paragraph shouldn't just say "B1 — some case errors." It should say something like:
In Ich habe mit mein Bruder gesprochen, mit takes the dative, so it should be meinem Bruder. You made this exact mistake twice — worth a focused review of dative prepositions this week.
That's actionable. A learner can turn it into a five-minute practice session. "B1 — some case errors" can't be turned into anything.
This is how the AI essay feedback in Lex is designed to work: a level estimate on top, a specific mistake list underneath, and — because your saved vocabulary, reading, and writing all sit in one place — the words and patterns you get corrected on show up again in your next reading text or writing prompt. The feedback becomes a loop, not a receipt.
Use the number, don't worship it
A CEFR letter from an AI is best read as a rough compass bearing, not a diploma. If it says B1 three sessions in a row, you're probably around B1. If it fluctuates between A2 and B2 depending on the prompt, the honest reading is: you're somewhere in that range, and the specific prompt shifted the grade.
The research is clear enough on this: AI can grade writing usefully, especially in the middle of the scale, especially when the feedback is specific. It's less useful when the number is treated as the point. The mistake list is the point. The level is context.
That's more or less how we'd hope any language tool worked — quietly informative, honest about its limits, and pointed at whatever you're actually going to do next.